What are you building?
Measured picks for each scenario, with live prices and no vendor spin.
- Chatbots A step-by-step chatbot build: model picker, a Stop that reaches the provider, a measured context budget, compression into memory, and gateway web search.
- Agent tracing Add three request headers to an agent's model calls and get a waterfall of each run: parallel calls, time spent in your own code, failed calls and cost.
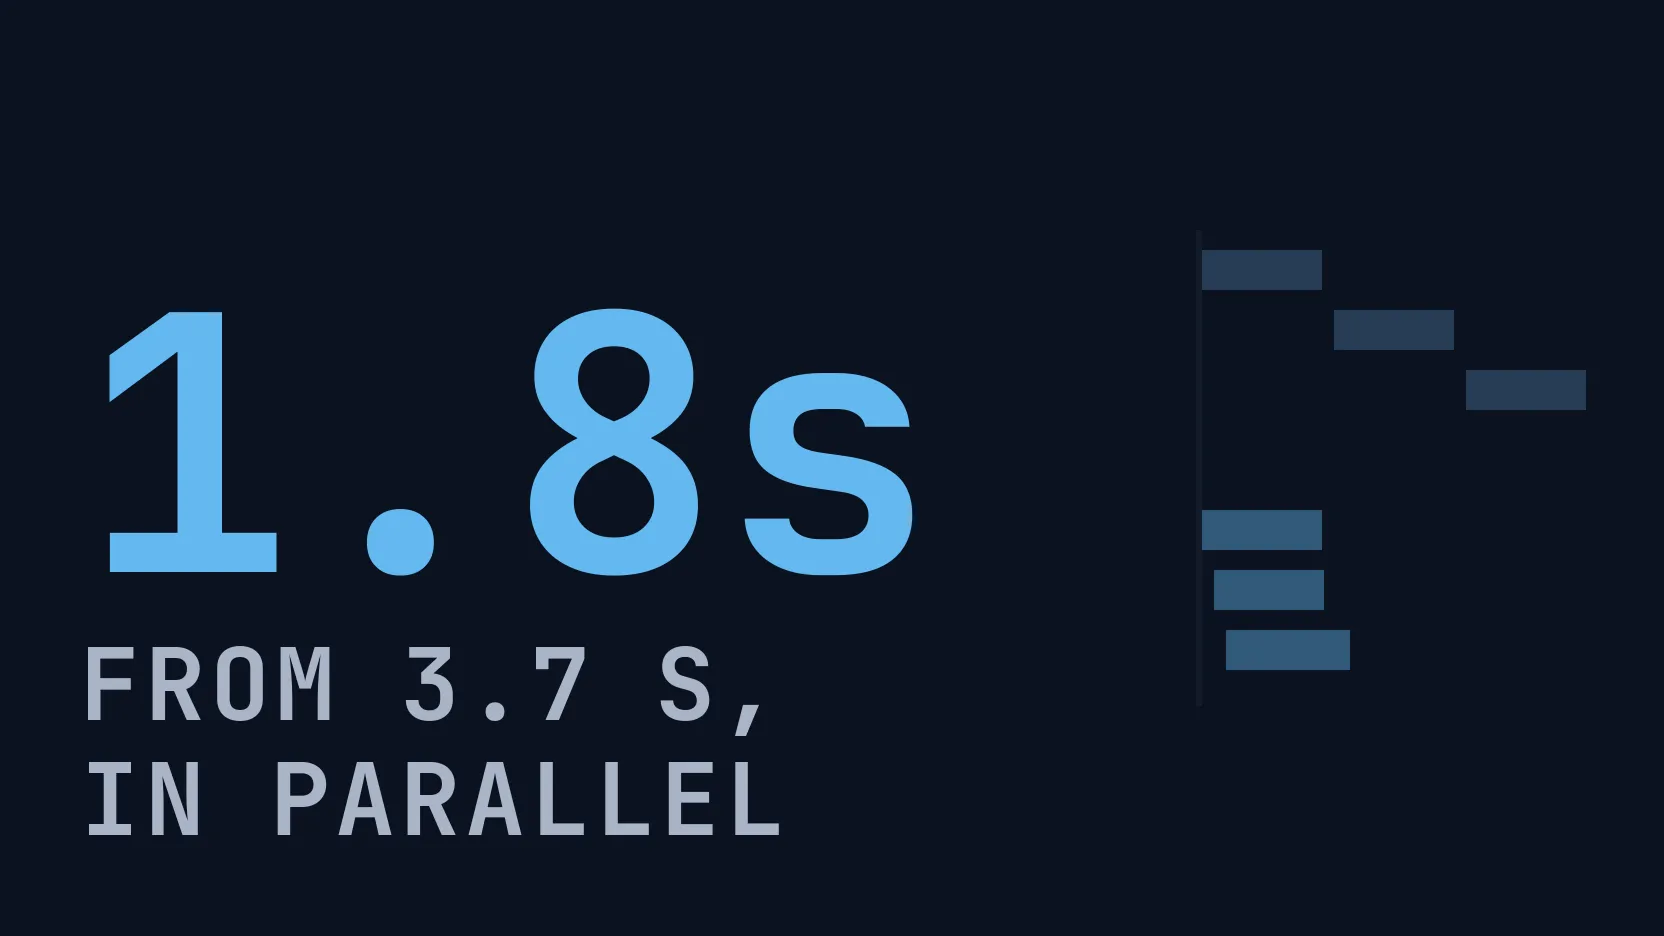
- Agent latency Three causes of a slow agent, each reproduced and fixed: serial model calls (3.7 s to 1.8 s), a slow tool in your own code, and reasoning on one-line answers.
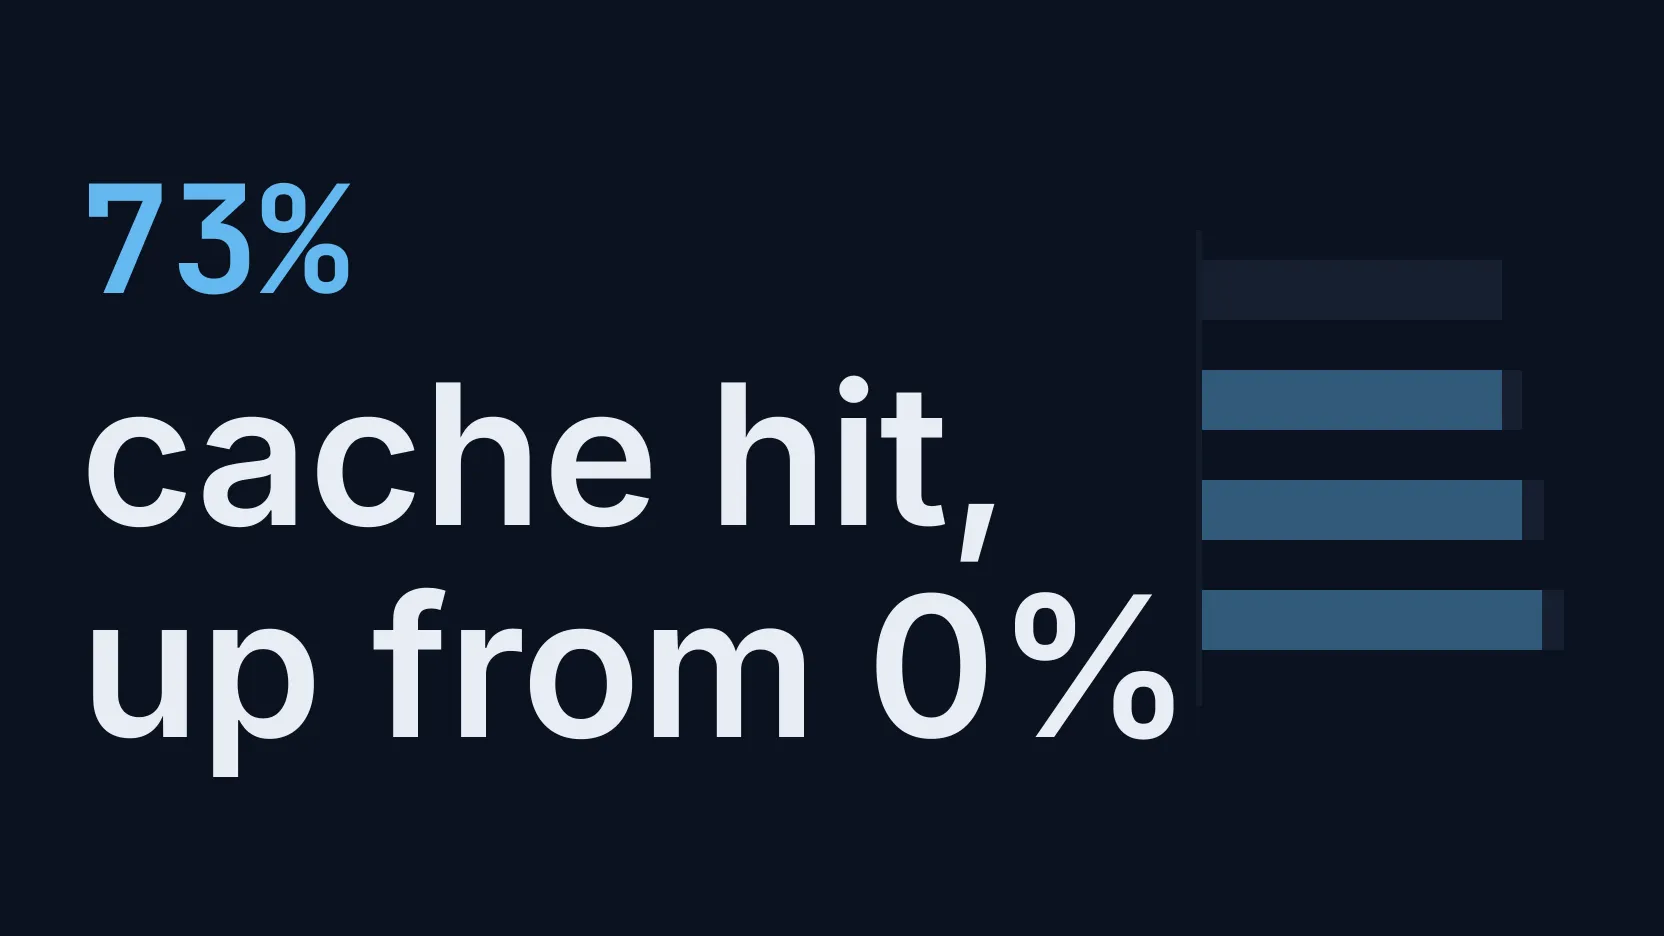
- Agent cost Four causes of a high agent bill, each reproduced and fixed: a cache-breaking timestamp (0% to 73% cache hit), growing context, a retry loop and a wrong model.
- Agent debugging Find one user's agent run by label, then read three failures in its trace: a 404 with a retry, replies cut off at status 200, and a 400 on the second turn.
- Coding agent spend One Claude Code run through a gateway, split by agent: the first call of each of three agents was 72% of a $0.17 bill. Setup is two environment variables.
- Agent log questions Add an LLM gateway to Claude as a custom connector, sign in, grant read access to the request log, and ask in chat. Three questions, 14 tool calls, checked.
- Agent log tools Give your own agent an LLM gateway's log tools over MCP with an API key. One cost investigation cost $0.0015 on a small model; a fixed REST query cost $0.
- Prompt versioning Keep LLM prompts in a library, call them by prompt_id, ship by moving a label. Measured: 8 to 9 s to reach live calls, the same 114.5 prompt tokens as inline.
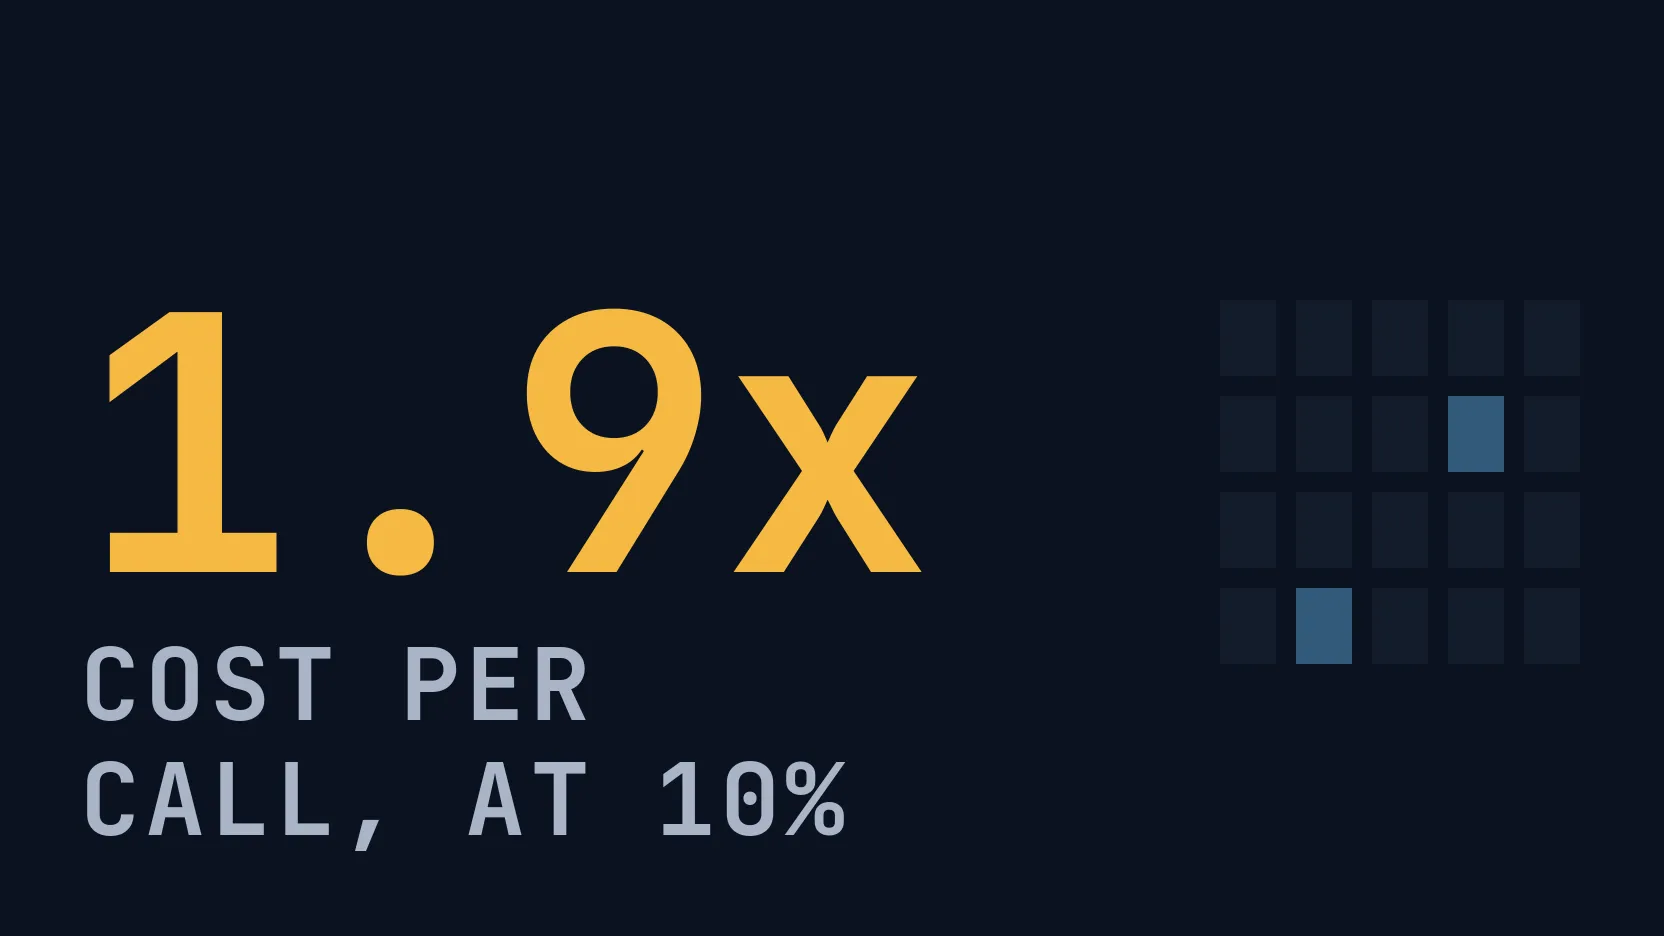
- Prompt rollout Send 10% of production to a new prompt version, split by session. Measured: 8.0% of 200 sessions went to it, all kept one version, and it cost 1.94x per call.
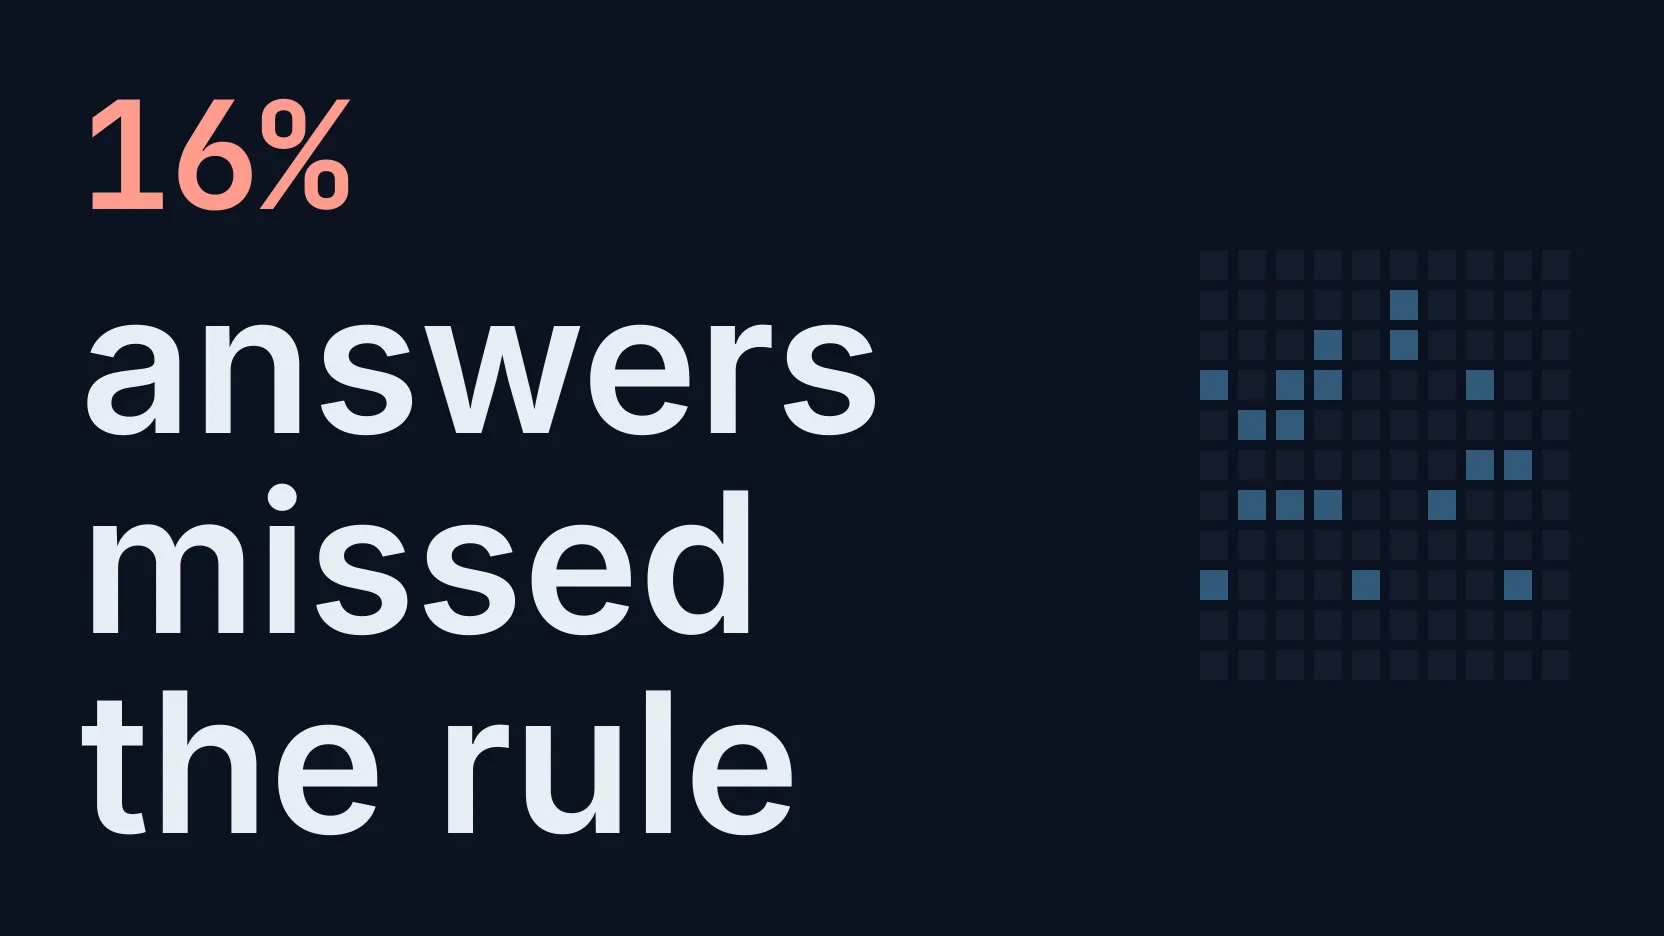
- Prompt testing A shorter prompt dropped one rule. On 110 new messages it left out the order number 18 times (16%) and the old one never, yet one 40-row run showed no misses.