
GPT Image 2 vs GPT Image 2.6 Sunburst
Which one, when
Try gpt-image-2.6-sunburst for detailed compositions with the complexity control. If an existing pipeline depends on the flexible dimensions of gpt-image-2, verify those sizes and compare reference-image usage before switching.
Pricing
| GPT Image 2 | GPT Image 2.6 Sunburst | Δ | |
|---|---|---|---|
| Input / 1M tokens | $5 | $5 | = |
| Output / 1M tokens | $30 | $30 | = |
| Reference image input / 1M tokens | $8 | $8 | = |
| Cache read / 1M tokens | - | $1.25 | - |
| Cached reference image input / 1M tokens | - | $2 | - |
Rates from the live catalogue at build time; each model page carries the current rate card.
Where they sit · output price per 1M tokens across all 15 image-generation models on this billing unit (log scale)
Specs
| GPT Image 2 | GPT Image 2.6 Sunburst | |
|---|---|---|
| Input modalities | text image | text image |
| Output modalities | image | image |
| Released | 2026-04-21 | 2026-11-04 |
| Output sizes |
|
|
| Input modes | text-to-image, image edit with mask inpainting | text-to-image and reference-image editing |
| Images per request | 10 | 4 |
| Formats | png, jpeg, webp | png, jpeg, webp, gif, svg |
| Notes | Flexible resolutions: edges up to 3840px in multiples of 16, ratio <=3:1, ~0.65-8.3MP total (incl. 4K 3840x2160) editing with mask inpainting all image inputs processed at high fidelity significantly improved text rendering (precise placement can still struggle) | Custom width and height must be multiples of 16, with an aspect ratio from 1:3 to 3:1. On Synthorai, send a reference image as base64 in the image field of a JSON request to /v1/images/generations. Set complexity to low, medium or high independently of quality. |
Specs are transcribed from each vendor’s documentation; a row a vendor does not publish is left out rather than inferred. Full sources: GPT Image 2 · GPT Image 2.6 Sunburst
One prompt, both models, measured through the gateway
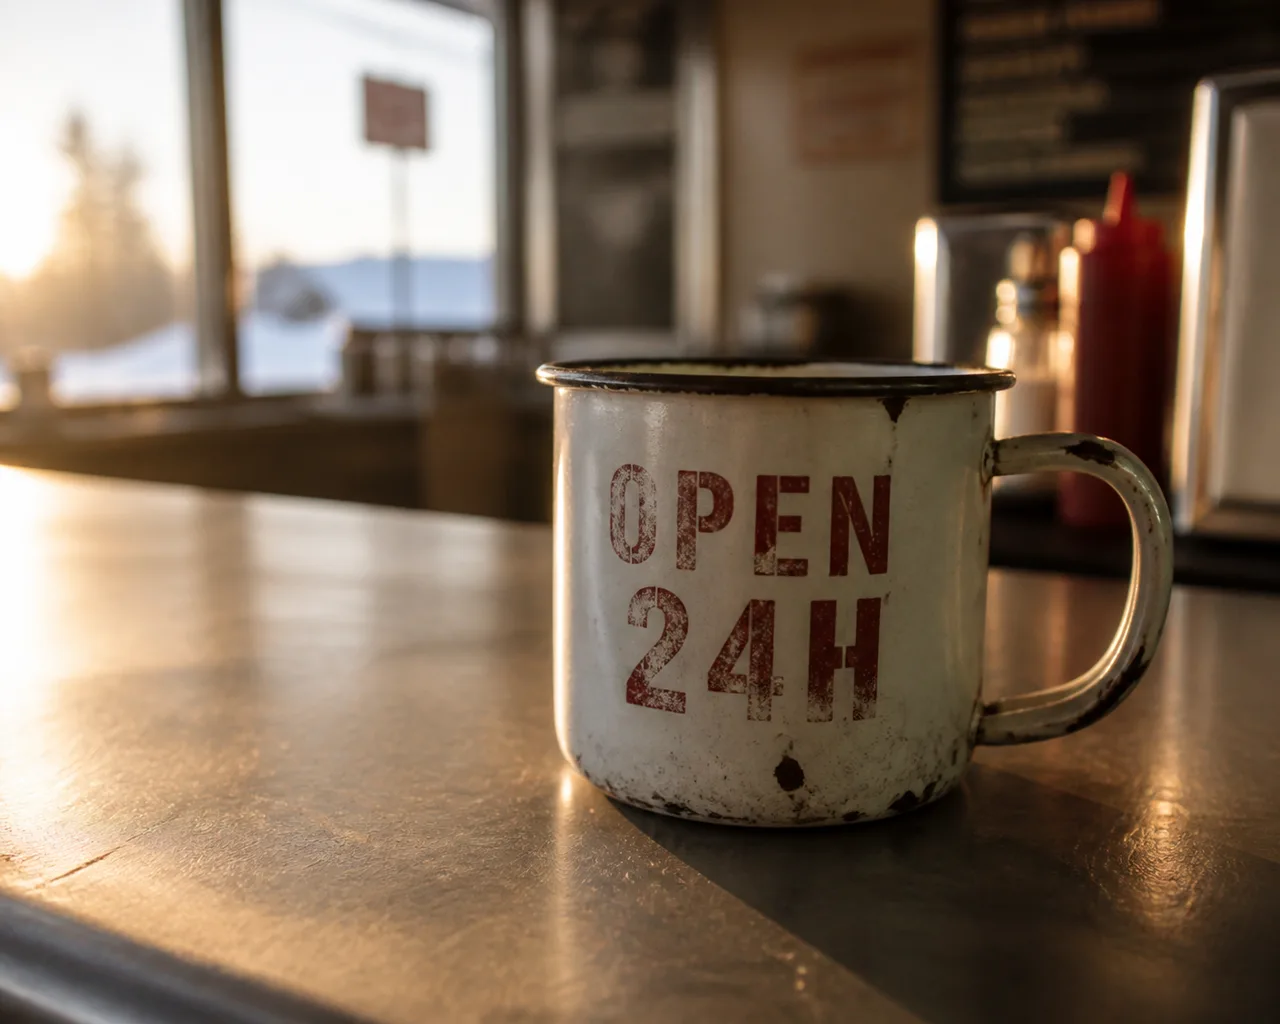
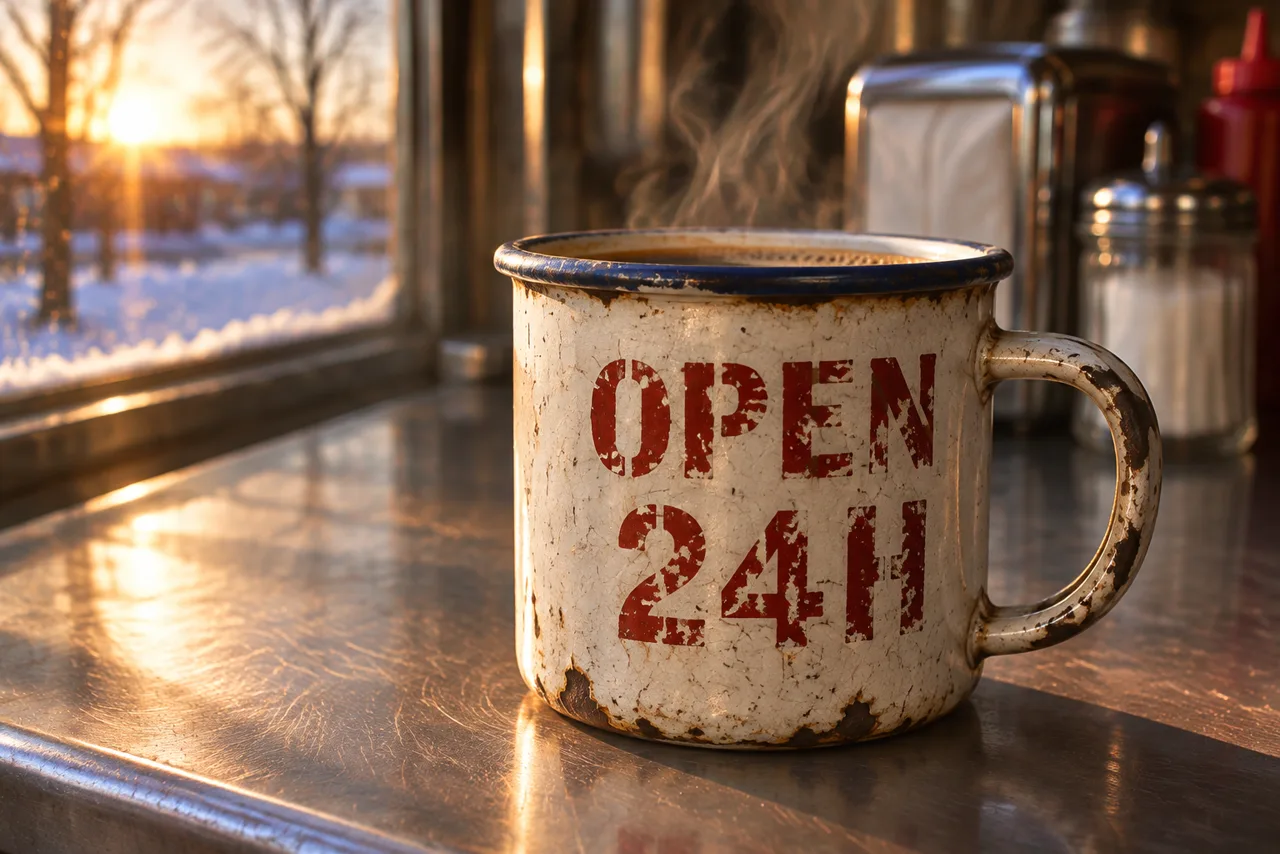
One prompt, one request per model, no retries and no cherry-picking. This is the first result each model returned. Neither size nor duration was pinned: each model used its own default, because a request shaped to fit all of them would flatter none. Files here are re-encoded for the web, so judge composition and prompt adherence, not compression.
Switch between them with one line
Both ids are in every tab below; the highlighted pair of lines is the only edit. Same endpoint, same key, same request shape.
from openai import OpenAI

client = OpenAI(
    base_url="https://synthorai.io/v1",
    api_key="sk-syn-...",
)

resp = client.images.generate(
    model="gpt-image-2",
    # model="gpt-image-2.6-sunburst",  # uncomment this line, comment the one above
    prompt="a watercolor lighthouse at dawn",
    size="1024x1024",
)
print(resp.data[0].b64_json[:80])
import OpenAI from "openai";
const client = new OpenAI({
baseURL: "https://synthorai.io/v1",
apiKey: "sk-syn-...",
});
const resp = await client.images.generate({
model: "gpt-image-2",
// model: "gpt-image-2.6-sunburst", // uncomment this line, comment the one above
prompt: "a watercolor lighthouse at dawn",
size: "1024x1024",
});
console.log(resp.data?.[0]?.b64_json?.slice(0, 80));curl https://synthorai.io/v1/images/generations \
-H "Authorization: Bearer sk-syn-..." \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-image-2",
# "model": "gpt-image-2.6-sunburst", # uncomment this line, comment the one above
"prompt": "a watercolor lighthouse at dawn",
"size": "1024x1024"
}'package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/option"
)
func main() {
client := openai.NewClient(
option.WithBaseURL("https://synthorai.io/v1"),
option.WithAPIKey("sk-syn-..."),
)
resp, _ := client.Images.Generate(context.TODO(), openai.ImageGenerateParams{
Model: "gpt-image-2",
// Model: "gpt-image-2.6-sunburst", // uncomment this line, comment the one above
Prompt: "a watercolor lighthouse at dawn",
Size: "1024x1024",
})
fmt.Println(resp.Data[0].B64JSON[:80])
}import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.images.*;
OpenAIClient client = OpenAIOkHttpClient.builder()
.baseUrl("https://synthorai.io/v1")
.apiKey("sk-syn-...")
.build();
ImagesResponse resp = client.images().generate(
ImageGenerateParams.builder()
.model("gpt-image-2")
// .model("gpt-image-2.6-sunburst") // uncomment this line, comment the one above
.prompt("a watercolor lighthouse at dawn")
.size("1024x1024")
.build());
System.out.println(resp.data().orElseThrow().get(0).b64Json().orElseThrow().substring(0, 80));FAQ
Which is cheaper, GPT Image 2 or GPT Image 2.6 Sunburst?
Both list $5 for “Input / 1M tokens”. Other rates and the number of units used can still change the total cost.
Can I A/B test GPT Image 2 against GPT Image 2.6 Sunburst without two integrations?
Yes. Both are served through the same OpenAI-compatible endpoint with one API key. Switching is a one-line change to the model id, so you can route a fraction of traffic to each and compare bills directly.
Does the price change with image size?
It depends on how the model bills. Per-image models charge the same regardless of prompt or output size; token-billed models scale with the resolution you render, so a 4K image costs a multiple of a small one. The table above shows which applies to each.