
Gemini 3 Pro Image, marketed as Nano Banana Pro, is Google's reasoning-driven engine for professional-grade image generation and editing, positioned for studio-quality visuals up to 4K with precise text rendering.
- Input
- text image $2/M
- Output
- image text $120/M
Price in context
Where the price sits among 9 comparable models
The bar shows how this model’s price compares with every other model of the same kind on Synthorai. The cheapest and the most expensive are named at each end. These are base rates; batch, region and cache-write discounts are on the pricing page.
Specs & limits
Tokens
| Context window (vendor spec) | 65,536 |
|---|---|
| Max output (vendor spec) | 32,768 |
Thinking
| Default | thinking on applied when the request sets nothing |
|---|---|
| Can be turned off | No |
| Thinking behaviour | A default thinking pass refines composition before generation and cannot be disabled in the API; it emits up to two interim thought images, which are not charged. Google publishes no thinking-level control for this model. |
| Parameter | reasoning_effort |
| Values | minimal · low · medium · high accepted set is the provider's |
Image
| Sizes |
|
|---|---|
| Input modes | text-to-image, image editing, up to 14 reference images |
| Image capabilities |
|
Model
| Modalities | text + image → image + text |
|---|
- Google's stable model code for Nano Banana Pro
- the gateway served it as gemini-3-pro-image-preview until 2026-10-09. Caching, function calling and structured outputs are not supported
- Search grounding and batch are. It reasons before every image and has no thinking-level control. Billed per token at three rates: input, image output, and text and reasoning output
- an output image is 1,120 tokens at 1K and 2K and 2,000 at 4K, and a reference image is 560 input tokens
One prompt, measured through the gateway
Gemini 3 Pro Image
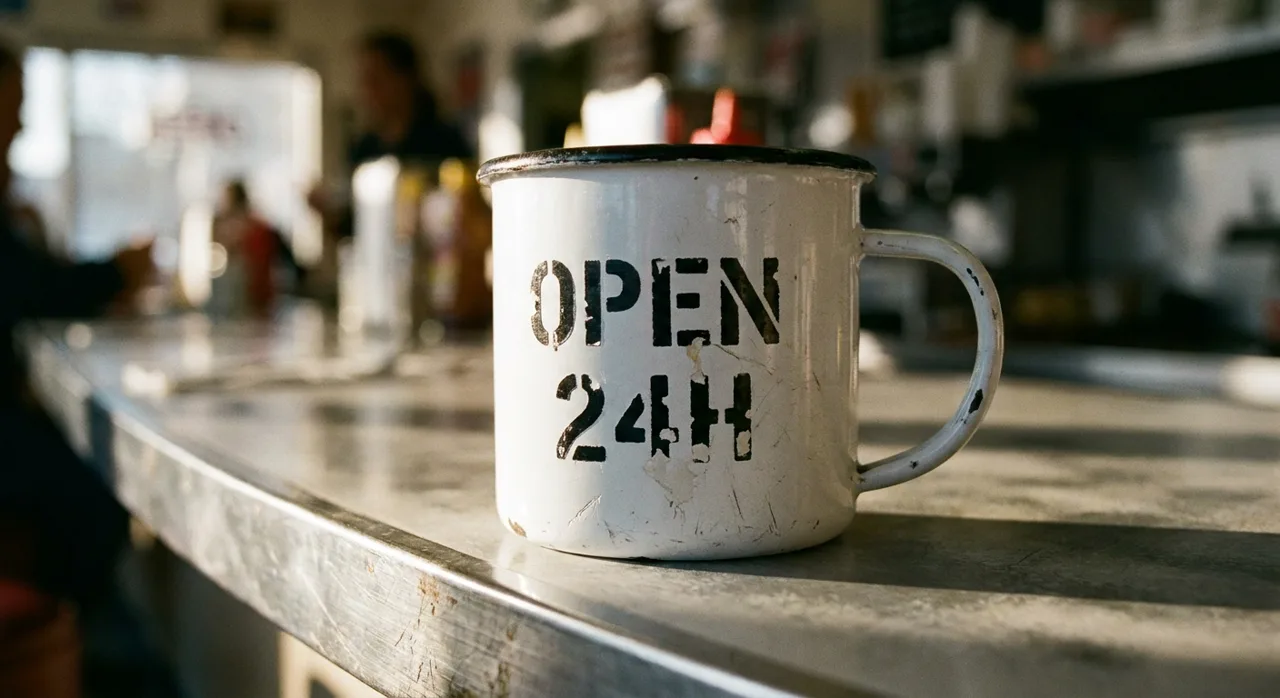
Model returned 1408×768 latency 18 s
One prompt, one request per model, no retries and no cherry-picking. This is the first result each model returned. Neither size nor duration was pinned: each model used its own default, because a request shaped to fit all of them would flatter none. Files here are re-encoded for the web, so judge composition and prompt adherence, not compression.
Use Gemini 3 Pro Image in 30 seconds
OpenAI-compatible: swap the base_url, keep your SDK. POST /v1/images/generations
from openai import OpenAI

client = OpenAI(
    base_url="https://synthorai.io/v1",
    api_key="sk-syn-...",
)

resp = client.images.generate(
    model="gemini-3-pro-image",
    prompt="a watercolor lighthouse at dawn",
    size="1024x1024",
)
print(resp.data[0].b64_json[:80])
import OpenAI from "openai";
const client = new OpenAI({
baseURL: "https://synthorai.io/v1",
apiKey: "sk-syn-...",
});
const resp = await client.images.generate({
model: "gemini-3-pro-image",
prompt: "a watercolor lighthouse at dawn",
size: "1024x1024",
});
console.log(resp.data?.[0]?.b64_json?.slice(0, 80));curl https://synthorai.io/v1/images/generations \
-H "Authorization: Bearer sk-syn-..." \
-H "Content-Type: application/json" \
-d '{
"model": "gemini-3-pro-image",
"prompt": "a watercolor lighthouse at dawn",
"size": "1024x1024"
}'package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/option"
)
func main() {
client := openai.NewClient(
option.WithBaseURL("https://synthorai.io/v1"),
option.WithAPIKey("sk-syn-..."),
)
resp, _ := client.Images.Generate(context.TODO(), openai.ImageGenerateParams{
Model: "gemini-3-pro-image",
Prompt: "a watercolor lighthouse at dawn",
Size: "1024x1024",
})
fmt.Println(resp.Data[0].B64JSON[:80])
}import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.images.*;
OpenAIClient client = OpenAIOkHttpClient.builder()
.baseUrl("https://synthorai.io/v1")
.apiKey("sk-syn-...")
.build();
ImagesResponse resp = client.images().generate(
ImageGenerateParams.builder()
.model("gemini-3-pro-image")
.prompt("a watercolor lighthouse at dawn")
.size("1024x1024")
.build());
System.out.println(resp.data().orElseThrow().get(0).b64Json().orElseThrow().substring(0, 80));About Gemini 3 Pro Image
- It targets graphic design, product mockups, and data visualization, and Google calls it the premium choice for the most complex visual tasks, citing the highest level of world knowledge, advanced localization, brand consistency, and precision creative control.
- The model accepts image and text input and returns interleaved image and text output, with 65,536 input and 32,768 output tokens, at 1K, 2K, or 4K across ten aspect ratios from 1:1 to 21:9.
- Thinking is the differentiator: the model generates up to two interim images to test composition and logic, and the last of those is the delivered render.
- Google Search grounding lets it pull real-time facts, such as current weather or market data, into a chart or layout before drawing.
- It accepts up to six object reference images, five character references, and three style references, and Google names it as its best model for legible in-image text, including localizing and translating copy across fonts and calligraphy.
- Batch processing is supported, and output carries SynthID plus C2PA Content Credentials.
- Synthorai delivers it through the same OpenAI-compatible endpoint as its other image models.
FAQ
Is the Gemini 3 Pro Image API free to try?
Yes: new accounts get 10 trial calls and up to $1 in free credit, no card required. That's enough to try Gemini 3 Pro Image against your real workload before adding a payment method.
What is Gemini 3 Pro Image best at?
Studio-quality visuals up to 4K; thinking plans complex compositions; search grounding keeps imagery factually anchored. See the About section for the full picture from the vendor's own release notes.
How much does Gemini 3 Pro Image cost?
Gemini 3 Pro Image costs $2 per million input tokens and $120 per million output tokens on Synthorai. That is the provider's list price, with no platform markup.
How do I generate images with the Gemini 3 Pro Image API?
POST to /v1/images/generations on Synthorai with model="gemini-3-pro-image". It follows the OpenAI images API shape, so no vendor SDK is needed. Supported sizes: 1K, 2K, 4K (1:1 = 1024x1024 / 2048x2048 / 4096x4096).
How do I get access to Gemini 3 Pro Image?
Point your existing OpenAI SDK at base_url="https://synthorai.io/v1", set model="gemini-3-pro-image", and you're done. One API key covers every model on the gateway.
Related models
Compare
Every value on this page is transcribed from the vendor's own documentation, linked above, and carries the date it was checked. Prices are compared across the catalogue; specification values that vendors define differently are shown with the difference stated rather than charted. Nothing here is measured by us, and nothing is scored.