
Gemini 3.1 Flash Image vs Gemini Nano Banana 2.1
Which one, when
gemini-nano-banana-2.1 is Google's update to gemini-3.1-flash-image, and the two headline rates move in opposite directions: image output drops from $60 to $30 per million tokens, while input rises from $0.5 to $1.5. Output dominates the bill for most image work, so the newer model is usually the cheaper one; the higher input rate matters only when a request carries a lot of input, such as video. Both take text, image and video input, return image and text, and accept up to 14 reference images. gemini-nano-banana-2.1 adds wide and tall aspect ratios (fifteen against ten) and has three thinking levels; gemini-3.1-flash-image keeps a 0.5K output size that the newer model does not list.
Pricing
| Gemini 3.1 Flash Image | Gemini Nano Banana 2.1 | Δ | |
|---|---|---|---|
| Input / 1M tokens | $0.5 | $1.5 | 0.33× |
| Output / 1M tokens | $60 | $30 | 2× |
Rates from the live catalogue at build time; each model page carries the current rate card.
Where they sit · output price per 1M tokens across all 11 image-generation models on this billing unit (log scale)
Specs
| Gemini 3.1 Flash Image | Gemini Nano Banana 2.1 | |
|---|---|---|
| Input modalities | text image video | text image video |
| Output modalities | text image | text image |
| Released | 2026-05-28 | 2026-10-06 |
| Output sizes |
|
|
| Input modes | text-to-image, single-turn and multi-turn editing, up to 14 reference images | text-to-image, single-turn and multi-turn editing, up to 14 reference images |
| Formats | jpeg, png | - |
| Notes | 0.5K, 1K, 2K and 4K output at ten aspect ratios (1:1, 3:2, 2:3, 3:4, 4:3, 4:5, 5:4, 9:16, 16:9, 21:9), JPEG or PNG up to 14 reference images per request, up to ten of them objects rendered with high fidelity plus character and style references single-turn editing and multi-turn conversational iteration | 1K, 2K and 4K output at fifteen aspect ratios (1:1, 3:2, 2:3, 3:4, 4:3, 4:5, 5:4, 9:16, 16:9, 21:9, 9:21, 1:4, 4:1, 1:8, 8:1) up to 14 reference images per request single-turn editing and multi-turn conversational iteration |
Specs are transcribed from each vendor’s documentation; a row a vendor does not publish is left out rather than inferred. Full sources: Gemini 3.1 Flash Image · Gemini Nano Banana 2.1
One prompt, both models, measured through the gateway
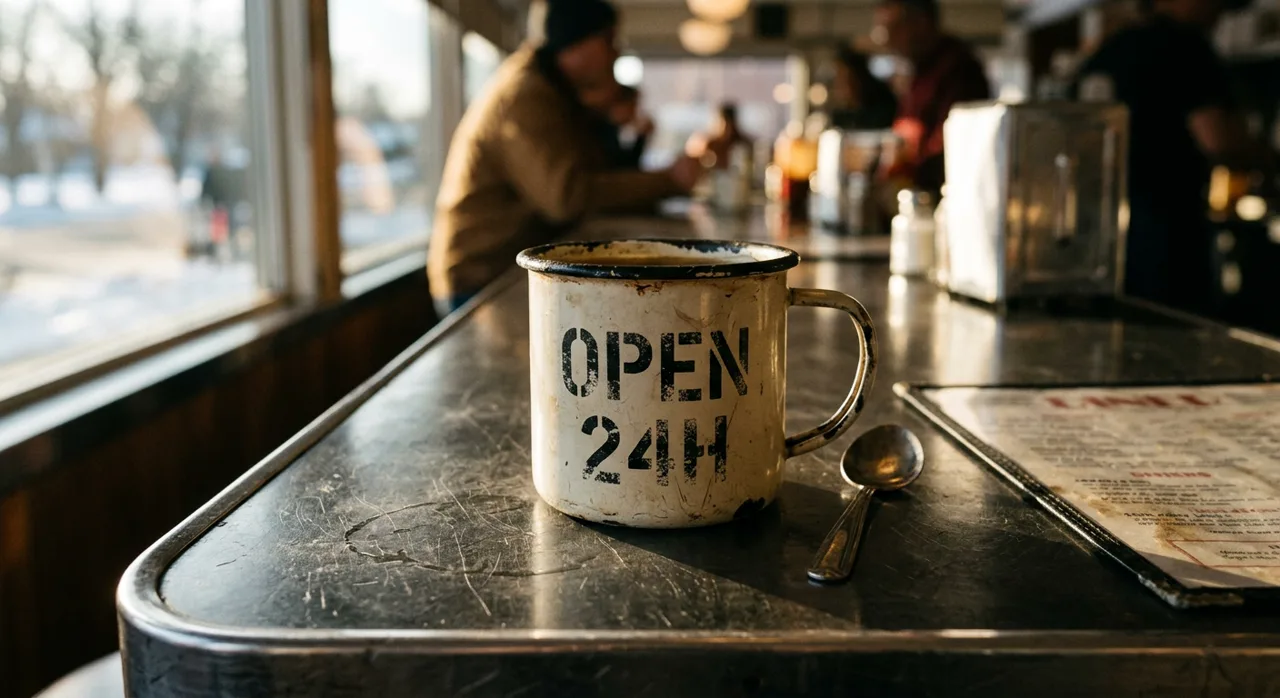
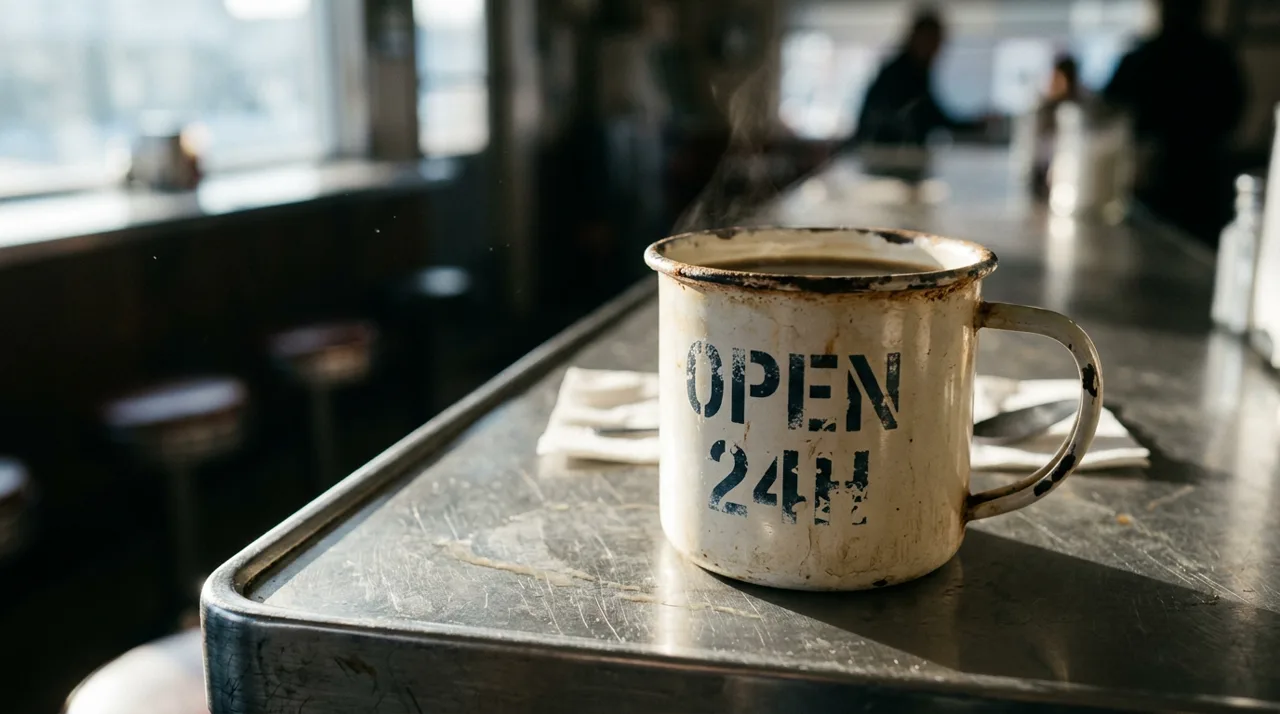
One prompt, one request per model, no retries and no cherry-picking. This is the first result each model returned. Neither size nor duration was pinned: each model used its own default, because a request shaped to fit all of them would flatter none. Files here are re-encoded for the web, so judge composition and prompt adherence, not compression.
Switch between them with one line
Both ids are in every tab below; the highlighted pair of lines is the only edit. Same endpoint, same key, same request shape.
from openai import OpenAI

client = OpenAI(
    base_url="https://synthorai.io/v1",
    api_key="sk-syn-...",
)

resp = client.images.generate(
    model="gemini-3.1-flash-image",
    # model="gemini-nano-banana-2.1",  # uncomment this line, comment the one above
    prompt="a watercolor lighthouse at dawn",
    size="1024x1024",
)
print(resp.data[0].b64_json[:80])
import OpenAI from "openai";
const client = new OpenAI({
baseURL: "https://synthorai.io/v1",
apiKey: "sk-syn-...",
});
const resp = await client.images.generate({
model: "gemini-3.1-flash-image",
// model: "gemini-nano-banana-2.1", // uncomment this line, comment the one above
prompt: "a watercolor lighthouse at dawn",
size: "1024x1024",
});
console.log(resp.data?.[0]?.b64_json?.slice(0, 80));curl https://synthorai.io/v1/images/generations \
-H "Authorization: Bearer sk-syn-..." \
-H "Content-Type: application/json" \
-d '{
"model": "gemini-3.1-flash-image",
# "model": "gemini-nano-banana-2.1", # uncomment this line, comment the one above
"prompt": "a watercolor lighthouse at dawn",
"size": "1024x1024"
}'package main
import (
"context"
"fmt"
"github.com/openai/openai-go/v3"
"github.com/openai/openai-go/v3/option"
)
func main() {
client := openai.NewClient(
option.WithBaseURL("https://synthorai.io/v1"),
option.WithAPIKey("sk-syn-..."),
)
resp, _ := client.Images.Generate(context.TODO(), openai.ImageGenerateParams{
Model: "gemini-3.1-flash-image",
// Model: "gemini-nano-banana-2.1", // uncomment this line, comment the one above
Prompt: "a watercolor lighthouse at dawn",
Size: "1024x1024",
})
fmt.Println(resp.Data[0].B64JSON[:80])
}import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.images.*;
OpenAIClient client = OpenAIOkHttpClient.builder()
.baseUrl("https://synthorai.io/v1")
.apiKey("sk-syn-...")
.build();
ImagesResponse resp = client.images().generate(
ImageGenerateParams.builder()
.model("gemini-3.1-flash-image")
// .model("gemini-nano-banana-2.1") // uncomment this line, comment the one above
.prompt("a watercolor lighthouse at dawn")
.size("1024x1024")
.build());
System.out.println(resp.data().orElseThrow().get(0).b64Json().orElseThrow().substring(0, 80));FAQ
Which is cheaper, Gemini 3.1 Flash Image or Gemini Nano Banana 2.1?
Gemini 3.1 Flash Image is cheaper on the "Input / 1M tokens" row ($0.5 vs $1.5, 3.0× apart). Other rows may point the other way; the table above carries the full rate card, and real cost depends on your mix.
Can I A/B test Gemini 3.1 Flash Image against Gemini Nano Banana 2.1 without two integrations?
Yes. Both are served through the same OpenAI-compatible endpoint with one API key. Switching is a one-line change to the model id, so you can route a fraction of traffic to each and compare bills directly.
Does the price change with image size?
It depends on how the model bills. Per-image models charge the same regardless of prompt or output size; token-billed models scale with the resolution you render, so a 4K image costs a multiple of a small one. The table above shows which applies to each.